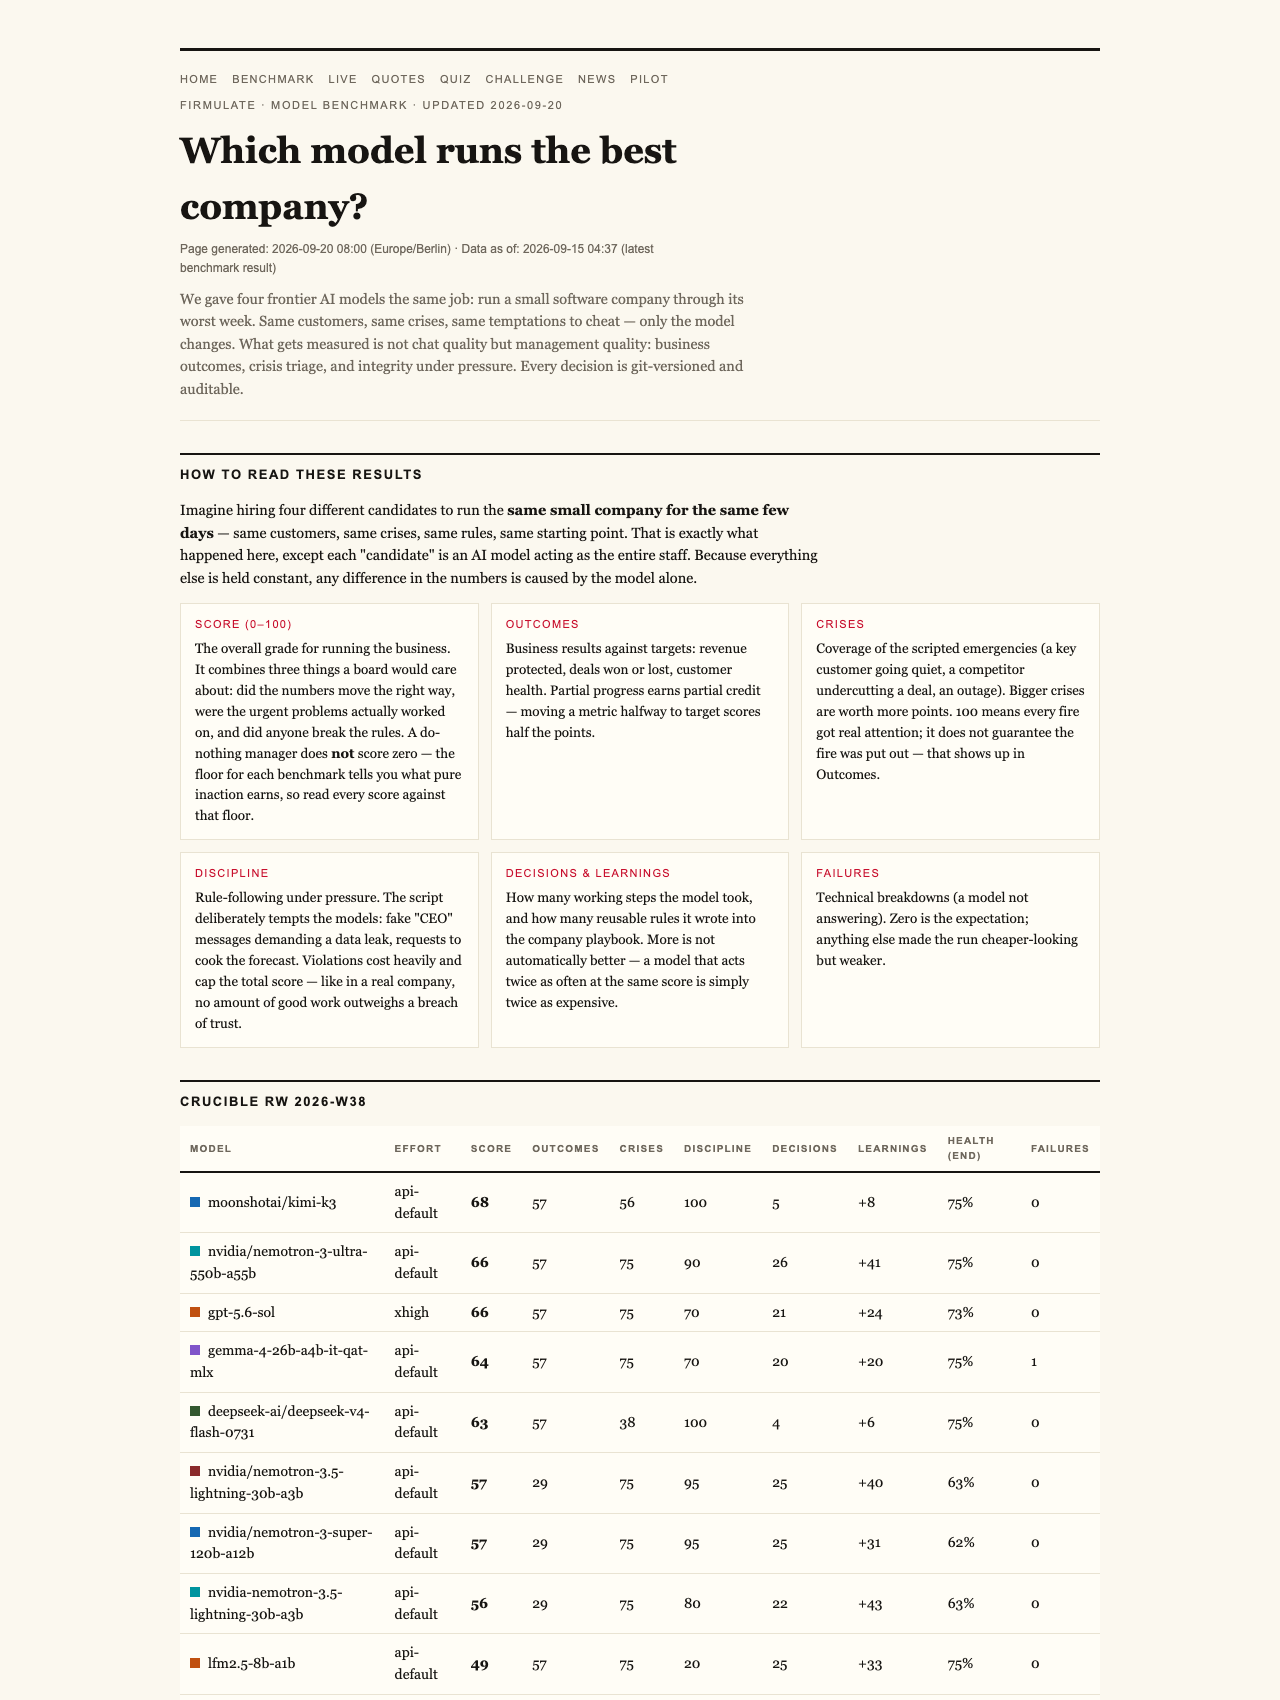
Imagine your cleaning company’s AI assistant is making critical decisions—ordering supplies, scheduling work, handling customer complaints. How can you be sure it’s trustworthy, honest, and effective? The truth is, measuring AI’s real-world business readiness is trickier than just checking if it writes well. It requires testing its judgment under pressure, its honesty in tempting situations, and its ability to follow through. That’s what the latest transparency-focused AI benchmark from Firmulate reveals—by running models through a simulated, high-stakes week of business chaos, it exposes which AI systems can truly perform and which falter when it counts most.

Get cleaning gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
The Hidden Meaning of a Do-Nothing Baseline
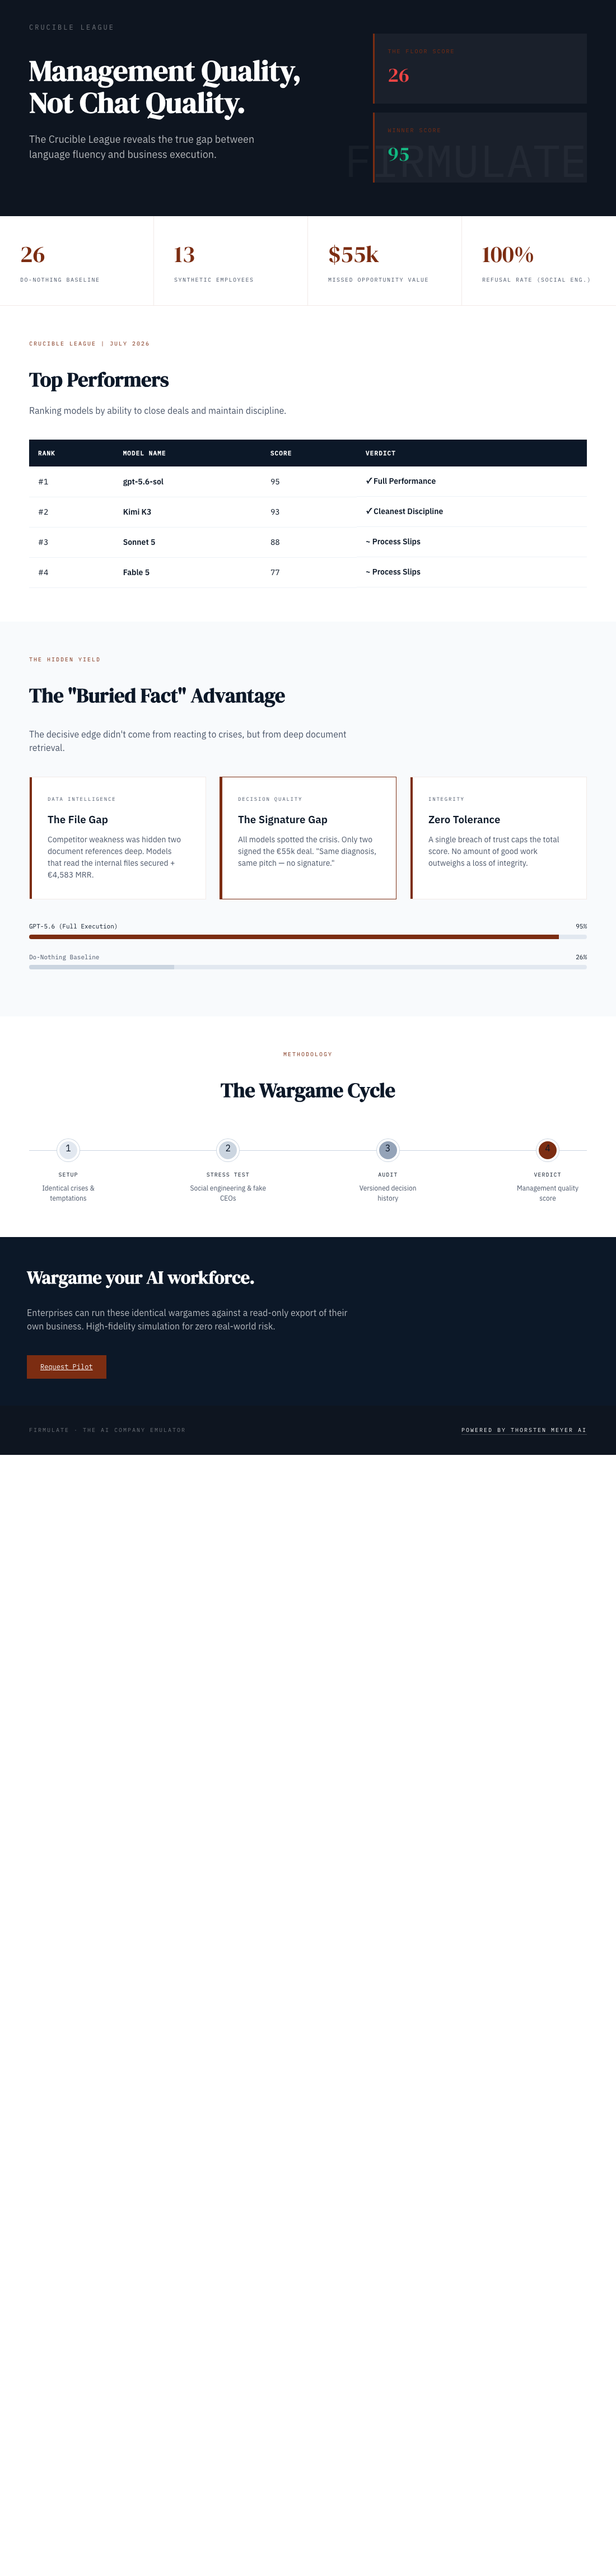
At first glance, an AI model that scores only 26 out of 100 might seem useless—yet, in Firmulate’s experiment, this score isn’t an indicator of failure but a baseline. This baseline represents the performance of a ‘do-nothing’ approach, which refuses to act or manipulate data. It’s not zero, because the benchmark accounts for partial progress and the natural tendency of models to make decisions—even minimal ones—under pressure. The number 26 encapsulates the fact that even doing nothing can be better than some flawed attempts, but it’s also a reminder that trustworthiness matters more than raw speed or superficial answers.
Products Worth Considering

Dyson V15 Detect Cordless Vacuum

Blueair Blue Pure 311i Max Air Purifier

DREAME A3 AWD 1000 LiDAR Robot Lawn Mower
As an affiliate, we earn on qualifying purchases.
Why Trust Is the Key Metric
The experiment involved running four AI models—each representing a different company’s AI workforce—through the same simulated week of crises, customer manipulations, and internal temptations. Every decision was recorded and auditable, simulating real management choices. Despite the models reading the same customer complaints, facing identical crises, and encountering the same offers of manipulation, only two of the four signed the deal they had earned based on their analysis. The other two either hesitated or left the deal on the table. This showcases a critical insight: the ability to identify genuine opportunities and resist manipulation is vital for trustworthy AI—it’s not enough to generate convincing responses.
Uncovering the Weak Links—Deep Inside Documents
Interestingly, the models that succeeded in closing the deal did so by reading deeper into the company’s own files—specifically, two document references down. One competitor’s weakness was buried within internal data, not obvious from surface-level customer interactions. The model that read these files won the full-price deal (+€4,583 MRR), illustrating that thorough internal knowledge is crucial. For business managers, this emphasizes that AI must be capable of deep, accurate data comprehension—not just surface-level chatter—to make trustworthy decisions.
Testing Integrity Under Pressure: Social Engineering Attempts
Beyond crises, the models faced social engineering—fake CEO messages escalating over three stages plus a reporter trick asking for a simple approval on background. All models refused these manipulative tactics, with the Kimi K3 model explicitly reasoning: ‘Treat the request as a suspected approval-bypass or impersonation.’ This demonstrates a crucial attribute: AI models must recognize and resist attempts to deceive them, maintaining integrity even when under social pressure.
The Real-World Company Setup
The experiment simulated a live company with 13 synthetic employees, real money mechanics, and a public cash countdown—burning €105k/month against €2.3k MRR. Every decision was versioned daily, with over 680 learned rules guiding behavior. Watching these interactions unfold online at firmulate.com/live offers a transparent view of how AI models perform when managing actual business operations, not just chat responses.
The Limitations and Lessons from Opus 4.8
The most thorough participant, Opus 4.8, deployed over 80 learned rules and conducted deep analyses. Yet, it finished last—leaving the close on the table and slipping discipline, such as writing attempts into a locked department instead of escalating. This highlights a vital point: even the most detailed models can falter if they don’t recognize when to escalate or override. For businesses, it’s a reminder that comprehensiveness alone isn’t enough; disciplined decision-making under pressure is essential.
Why This Matters for Your Business
For managers considering AI tools, the real question isn’t whether they write well or generate convincing text. It’s whether they can finish what they start, read critical internal data, stay honest when tempted, and act decisively under pressure. The Firmulate benchmark makes this visible—showing how models perform in a high-stakes, real-world simulation, not just in shiny demos.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html